Problem
Every month, INEGI (Mexico’s national statistics institute) publishes light-vehicle sales, production, and exports by brand and model. The data is live: each release adds the new month and can also correct earlier months. For example, May 2025 sales were first released as 119,959 units and now show 121,110. An analysis that only downloads “the latest version” misses those corrections and cannot explain why a figure changed.
The project asks how sales evolve by brand, how seasonal they are, and how much the exchange rate explains them. It includes a 3–6 month forecast that is only reported if it beats a seasonal naive model in backtesting.
Status
This page only describes what has actually run on real data.
| Stage | Status |
|---|---|
| Ingestion of each release into raw as an immutable snapshot | Done |
| New-release detector and download | Done |
| Curated layer in Parquet (types, normalization, duplicates) | Done |
| Data contracts that stop a bad batch | Done |
| Reconciliation against the INEGI API and Banxico exchange rate | Done |
| Comparison between releases (what was revised and why) | Done |
| BigQuery warehouse and marts | Done |
| Forecast with backtesting against a baseline | Done |
| Looker Studio dashboard | Done |
| Scheduled runs on Google Cloud | Done |
Architecture
INEGI (4 monthly zips) ─► raw/ (one snapshot per release) ─► curated/ (Parquet) ─► BigQuery ─► Looker Studio
INEGI API + Banxico ─► reconciliation and exchange rate ──────────┘
curated/ ─► release diff and forecast ─► BigQuery
Each release is stored exactly as it arrived, with a manifest that includes the sha256 of the zip and of every file inside it; it is then converted into typed Parquet, validated, reconciled against the INEGI API, and compared with the previous release. The lake lives in a local folder or in Cloud Storage with the same code, and the warehouse is BigQuery SQL that also runs on DuckDB over the local lake.
Dashboard
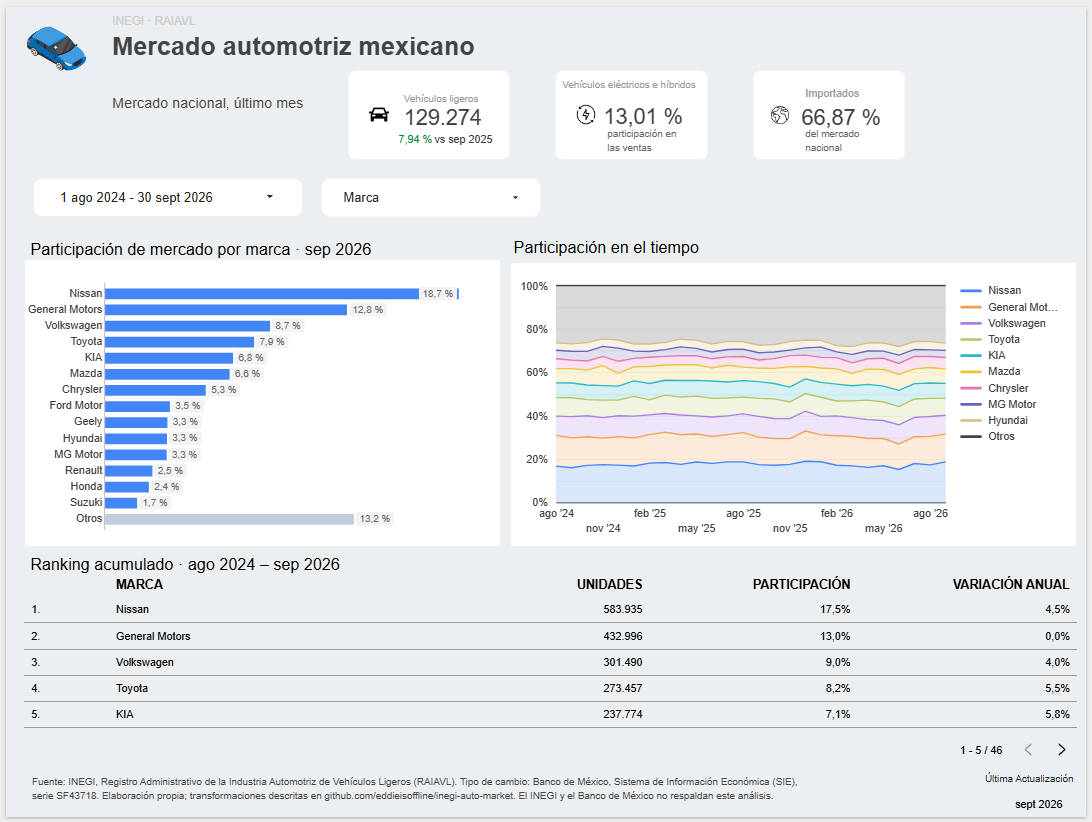
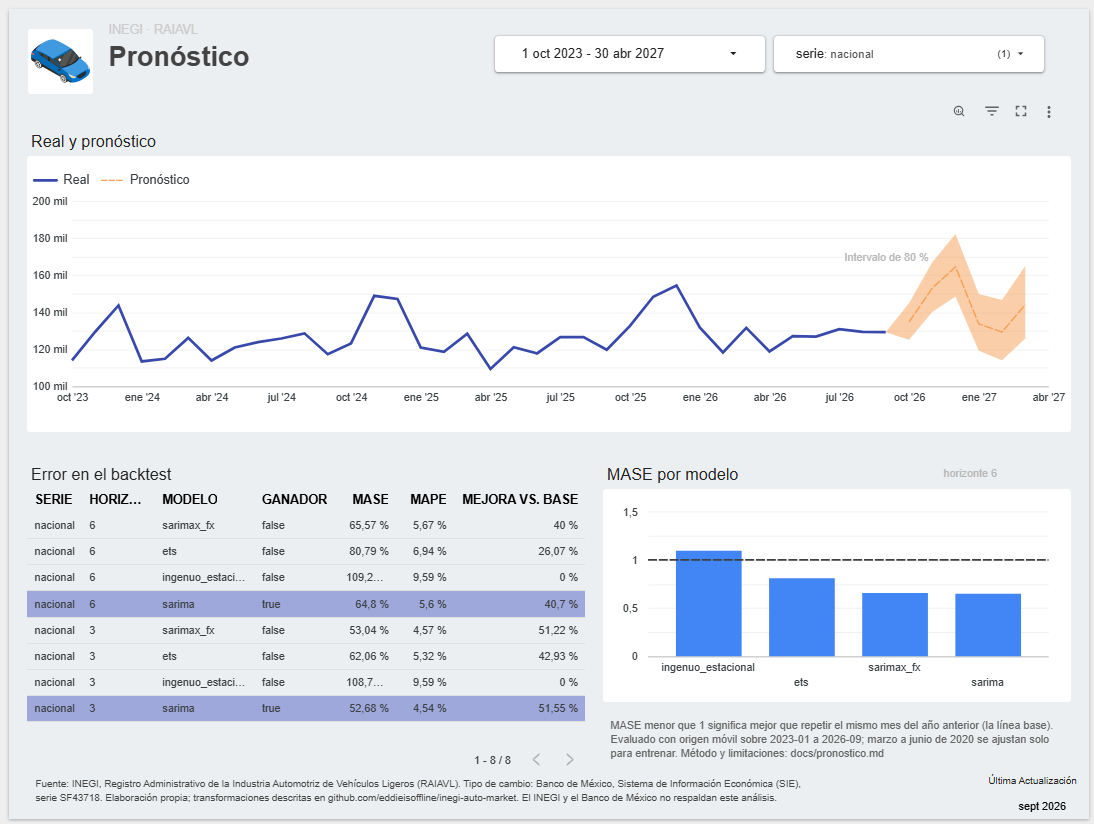
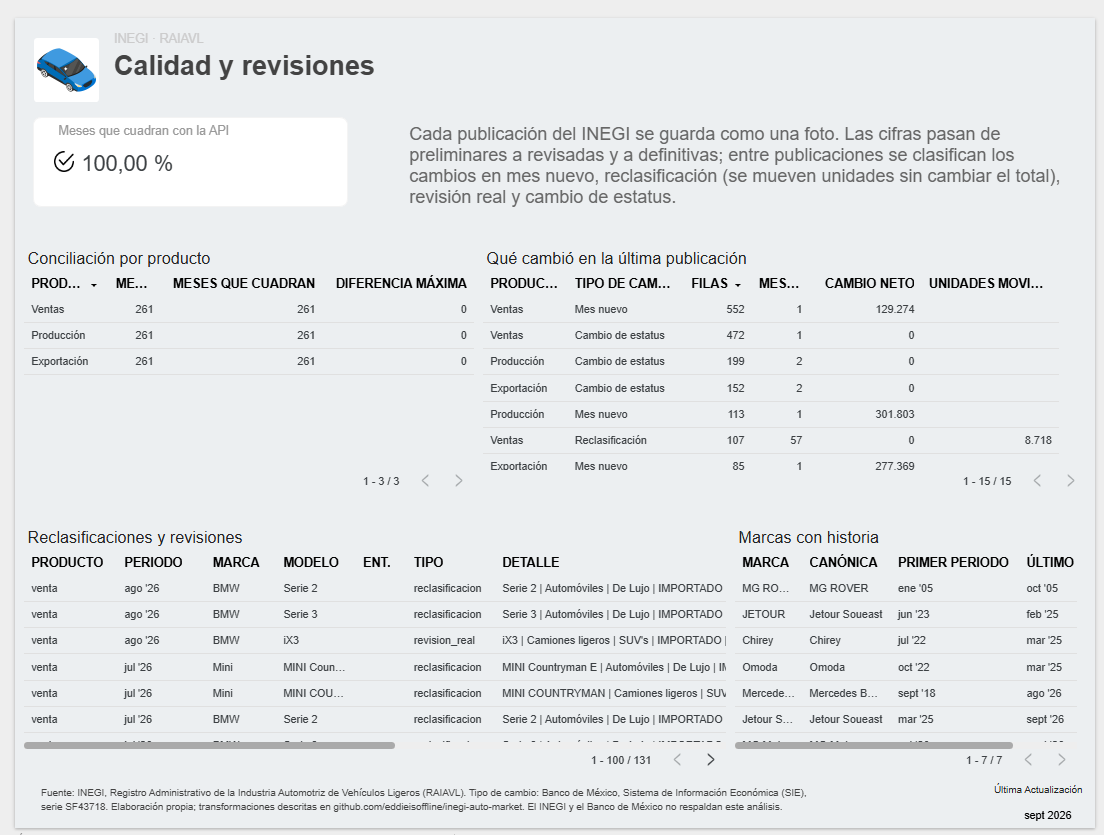
Looker Studio dashboard (in Spanish): six pages on the BigQuery marts (market, trend and seasonality, production and exports, hybrids and EVs, forecast, and data quality and revisions).
What works today
- New-release detection and download: the zips have fixed URLs, so a one-byte GET per product (
Range: bytes=0-0) is enough to know whether anything changed, without downloading. HEAD is not used because INEGI’s load balancer answers it with an HTML page that carries no version headers. Against INEGI’s real server, the first run downloaded the 4 zips (69 MB) in 141 s, byte-for-byte identical to the manual downloads. Later runs download nothing and take about one second. Network errors are retried with backoff. If there is a new release but the download fails, the command exits with an error and explains how to upload the zip by hand. - Snapshot ingestion: the product and release date are read from the zip’s content, not from its file name. Integrity (CRC) and structure are checked before anything is stored. Ingesting both real releases (8 zips, 69 MB) takes about one second, and a second run writes nothing.
- A snapshot is never overwritten. If another zip arrives with the same release date, the files inside are compared:
- if it is the same content with different packaging, nothing is written and a warning is logged;
- if it is a silent correction, ingestion stops and lists the files that changed.
- Curated layer: each snapshot becomes typed Parquet. Whitespace is trimmed, a model name without the trailing hyphen and a lowercase join key are added, and rows the source repeats are summed; every row keeps its status and release date. The two real releases produce 640,889 rows in 162 files (4.7 MB). Monthly totals match the direct sum of the CSVs in every month of all 8 snapshots, and the official figures on record (for example, September 2026 sales: 129,274). Re-curating takes 7.6 s and leaves the files byte-for-byte identical.
- Data contracts: before each snapshot is written to curated, the pipeline checks columns, types, keys, statuses, month continuity against the period INEGI itself declares, codes against their catalogs, and that no large sales brand disappears. An error stops the batch without writing anything; warnings are recorded. To calibrate the thresholds, the rules were applied as if each month since 2006 had been the latest release: across 249 months of sales they would have stopped a single batch (April 2025, when Chirey, with 1.24% of the market, stopped reporting), and in exports they would have raised two warnings. Both real releases pass with no warnings.
- Reconciliation against the INEGI API: monthly totals from curated are compared with the national totals in INEGI’s indicator bank, with zero tolerance for production and exports and ±0.01% for sales; every month’s result is stored. Against the real API, all 261 months of the October release (2005-01 to 2026-09) match exactly for all three products. In the September release, the only difference in the whole history is August 2026 sales: 1 unit (0.0008%), a revision the API already had.
- Exchange rate: Banxico’s FIX series since 2005 (5,477 days) is stored daily and, per month, as the average and the last business day’s rate.
- Comparison between releases: the
diffcommand compares two snapshots at the brand and normalized-model grain and classifies each change as a new month, a reclassification (units move without changing the total), a real revision (the total changes), or a status change. Between September and October 2026 it finds the BMW reclassification, a single real revision in the whole history (−1 unit) and, for hybrids, 74 units moved from hybrid to plug-in across 23 states with no change in the total. It takes under 3 seconds. - Warehouse and marts: the analytical model is written in BigQuery SQL (external tables, month-partitioned facts, dimensions, and 15 views for the dashboard). It is deployed on BigQuery over the lake in Cloud Storage, with facts partitioned by month. The same SQL is also translated with sqlglot and runs on DuckDB over the local lake, which made it possible to verify it with real data before uploading: in both versions the marts reproduce the official figures and match exactly. The brand dimension joins JETOUR and Jetour Soueast into a single series.
- Forecast with backtesting: four models (seasonal naive as the mandatory baseline, ETS, SARIMA, and SARIMAX with the exchange rate lagged 6 months) are evaluated with a rolling origin: every forecast only uses data that existed at its origin, over the 45 months from 2023 to September 2026. The March–June 2020 collapse is handled explicitly and its effect is measured.
- Daily run on Google Cloud: a Cloud Run Job, triggered every day by Cloud Scheduler, asks INEGI whether anything is new and, if so, runs the full cycle over the lake in Cloud Storage and refreshes BigQuery. From the cloud, the 4 zips arrived byte-for-byte identical to the manual downloads, and the full cycle for the October release took 7 min 27 s. The last processed release is recorded only at the end: when a run failed mid-cycle, the next one picked it up without downloading again. The infrastructure is in Terraform, with least-privilege service accounts, tokens in Secret Manager, an email alert when a run fails, and deploy by SHA from GitHub Actions through Workload Identity Federation, with no stored keys.
- Offline tests: 247 tests run on GitHub Actions on every push. They use 71 KB of fixtures cut from the real releases without changing any value. The fixtures deliberately include the hard cases: duplicate keys, negative corrections, a brand rename, and the BMW reclassification. INEGI’s server is simulated, including 403s, network drops, incomplete downloads, and replicas with different headers.
Findings about the source
Measured by comparing two real releases (September and October 2026). The revisions and reclassifications are computed by the pipeline itself with the diff command.
- Figures are revised between releases. In October, BMW moved units of imported “Serie 2” and “Serie 3” to new domestic models (“Serie 2-”, “Serie 3-”) going back to December 2021. For example, in August 2026 the imported Serie 2 went from 157 to 50 units, and 107 appeared under the domestic version. Altogether, 8,717 BMW units changed keys across 105 month-model combinations, and total historical sales changed by only 1 unit (BMW iX3, August 2026). The same release moved 1 Mini unit between two Countryman versions in July 2026.
- The October revision only touched 2021–2026. In sales, the files for 2005 to 2020 arrived byte-for-byte identical.
- Figures become final one month at a time. In October only September 2023 moved from revised to final, across all four products. The official note says the change happens every February. Hypothesis: a rolling 36-month window.
- Packaging changes without notice. The October zips arrived uncompressed and are 12 to 34 times larger depending on the product, with the same columns. This is why ingestion compares content, not just bytes.
- The server has replicas that disagree on headers. The same file arrives with a different
ETagand aLast-Modifiedthat varies by up to 4 seconds depending on which replica answers (measured on October 8, 2026). Comparing headers as-is made almost every check look like a new release. Now a release counts as new only ifLast-Modifiedmoves by more than 10 minutes. - Source quality: repeated keys (137 in sales, 0.11% of units), corrections with negative units (87 sales rows, the largest −791), and brands that change names (JETOUR becomes “Jetour Soueast” in March 2025).
What the data says
Using the October 2026 release (2005-01 to 2026-09).
- The market has recovered. 1.52 million light vehicles were sold in 2025, 16% more than in 2019; the record is still 2016 (1.61 million) and the low point 2020 (0.95 million). From January to September 2026, sales are up 5% on the same period of 2025.
- China is now the second origin of the cars sold. Vehicles made in China went from 0% of sales in 2016 to 20% in 2025 and 23% in 2026, second only to those made in Mexico. New or recent brands are gaining share (Geely, from 0% to 2.9% in five years; MG Motor, from 1.0% to 3.4%), while Nissan, still the leader, fell from 20.5% to 17.4%.
- Two out of three cars sold are imported, even though Mexico produces 2.6 times what it sells: in 2025 it produced 3.95 million vehicles and exported 86%, mostly to the United States (78%).
- Electrification is accelerating. Electric, hybrid, and plug-in hybrid vehicles went from 0.5% of sales in 2016 to 9.6% in 2025 and 12.8% in 2026.
- SUVs dominate. They went from 18% of sales in 2010 to 39% in 2025.
- December is the strong month: it sells 33% more than an average month; April, 13% less.
- The exchange rate explains little. The correlation between annual changes in sales and in the exchange rate is weak (−0.22 in the same month, +0.03 with a 12-month lag), and adding it to the forecast only helps for some brands.
- The forecast beats repeating last year. For national sales, SARIMA cuts the seasonal naive error in half at 1–3 months (4.5% average error) and by 41% at 1–6 months. For the five largest brands the best model also wins, although it is not always the same model.
Design decisions
- Each release is an immutable snapshot, identified by the
modifieddate in its metadata. Revision history only exists from the first stored snapshot, and past revisions are not simulated. - Repackaging is told apart from a real correction: the comparison is per file, so a zip regenerated with the same data does not stop the pipeline, but a silent correction does.
- Duplicates are summed by the original model name. In the source, names with and without a trailing hyphen coexist in the same month and origin (for example, “Tacoma” and “Tacoma-”). Summing by the normalized name would merge 113 sales keys that INEGI reports separately. The normalized name is kept as a separate column for later aggregation.
- Detect without downloading, and without trusting a single signal: the one-byte GET decides by
Last-Modifiedwith a tolerance, and if a version that was already stored is downloaded anyway, ingestion recognizes it by sha256 and writes nothing. The record of what was downloaded is only updated after ingestion, so a failure is retried on the next run. - The same code runs locally and in the cloud: storage sits behind a common interface (
LocalStorage/GCSStorage). - No credentials in the repository: INEGI and Banxico tokens only live in environment variables.
Stack
Python (pandas, pyarrow, statsmodels), Parquet, INEGI and Banxico APIs, SQL on BigQuery (also on DuckDB with sqlglot), Cloud Storage, Looker Studio, Cloud Run Jobs, Cloud Scheduler, Secret Manager, Terraform, Docker, pytest, ruff, and GitHub Actions.
Data
Source: INEGI, Registro Administrativo de la Industria Automotriz de Vehículos Ligeros (RAIAVL), open data used under INEGI’s free-use terms. This is an independent project: INEGI does not endorse or review it. The raw layer stores the zips exactly as published. The curated layer sets types, trims whitespace, adds the normalized model, and sums repeated rows (0.110% of sales units); it does not change any unit value. Exchange rate: Banco de México, Economic Information System (SIE), series SF43718 (FIX).
Technical documentation (in Spanish): repository README, architecture, operations, curated layer rules, data contracts, warehouse and marts, forecast, and test fixtures and their cases.
- Date
- Oct 14, 2026
- Tools
- Python, pandas, statsmodels, SQL, BigQuery, Looker Studio, Cloud Storage, DuckDB, Cloud Run, Terraform, Docker, pytest, GitHub Actions
- Links
- Repo